Last updated on
Flink Doris Connector
Flink Doris Connector reads from and writes to a Doris cluster through Flink, and integrates Flink CDC to conveniently complete full-database synchronization from upstream databases such as MySQL.
Capabilities
| Capability | Description | Typical scenarios |
|---|---|---|
| Reading Data from Doris | Reads from BEs in parallel without routing data through FE; supports the Thrift and Arrow Flight SQL protocols | Using a Doris table as the input of a Flink job, bulk export |
| Incremental Reading with Doris Binlog | Continuously consumes the row-level changes (insert, update, delete) of a table, optionally starting from a snapshot; requires Connector 26.3.0+ and Doris 5.0.0+ | Syncing the changes of a Doris table to downstream systems in real time |
| Writing Data to Doris | Batches data in Flink and writes it through Stream Load; offers streaming write (Checkpoint-based, Exactly-Once), batch write, and S3 TVF write | Real-time ingestion, landing CDC changes, partial column updates |
| Lookup Join | Batches upstream records and queries the Doris dimension table asynchronously | Enriching streams with dimension data |
| Full-Database Sync | Integrates Flink CDC to sync an entire MySQL, Oracle, PostgreSQL, SQLServer, DB2, or MongoDB database with one command, creating tables and syncing DDL automatically | Syncing business databases to Doris in real time |
All capabilities are available through FlinkSQL; reading and writing are also available through the DataStream API. See Connection Options and TLS for connection settings and Data Type Mapping for how Doris and Flink types correspond.
How It Works
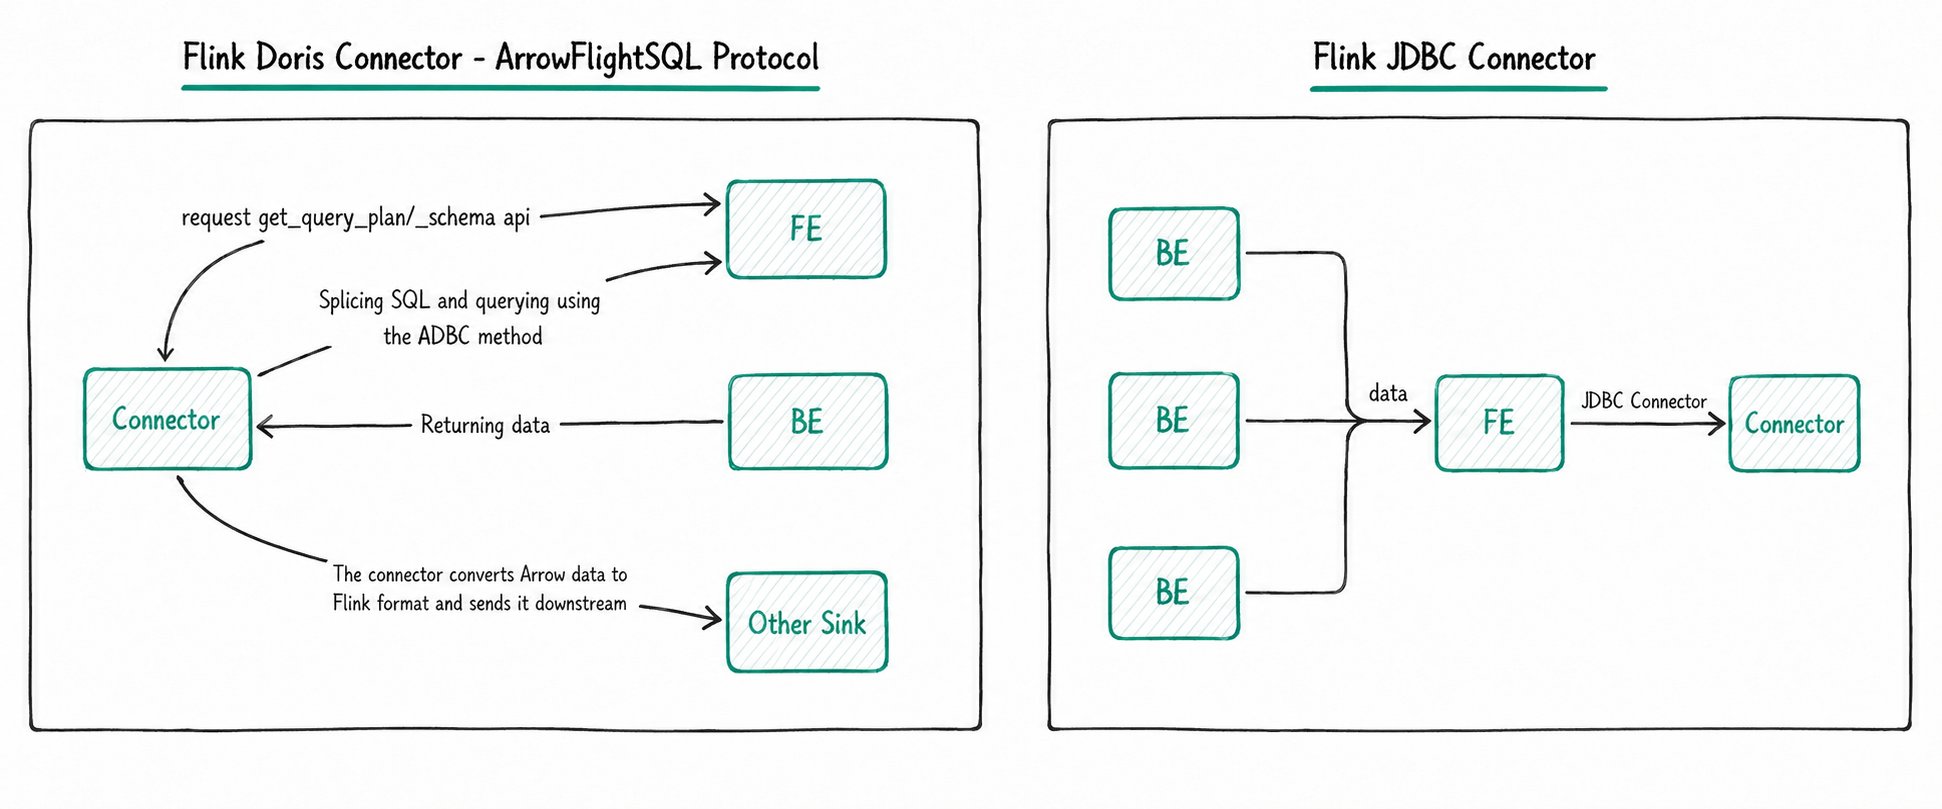
- Read: The Connector obtains the Tablet information of the query plan from FE, then reads data from the BEs directly and in parallel. Data does not flow through FE, which avoids the bottleneck of reading and writing serially on a single FE node through JDBC. See Read Principle.
- Write: Data is batched in Flink memory and then bulk-loaded into Doris through Stream Load. By default, writes follow Flink Checkpoints and use two-phase commit to guarantee Exactly-Once; a batch write mode that does not depend on Checkpoints is also available. See Write Modes.
- Lookup Join: Upstream records are batched and the Doris dimension table is queried asynchronously, instead of one point query per record.
- Full-database sync: Changes are read from the upstream database with Flink CDC and written through the Doris Sink, which creates the target tables and syncs Schema Changes automatically.
Version Notes
| Connector Version | Flink Version | Doris Version | Java Version | Scala Version |
|---|---|---|---|---|
| 1.0.3 | 1.11,1.12,1.13,1.14 | 0.15+ | 8 | 2.11,2.12 |
| 1.1.1 | 1.14 | 1.0+ | 8 | 2.11,2.12 |
| 1.2.1 | 1.15 | 1.0+ | 8 | - |
| 1.3.0 | 1.16 | 1.0+ | 8 | - |
| 1.4.0 | 1.15 - 1.17 | 1.0+ | 8 | - |
| 1.5.2 | 1.15 - 1.18 | 1.0+ | 8 | - |
| 1.6.1 | 1.15 - 1.19 | 1.0+ | 8 | - |
| 24.0.1 | 1.15 - 1.20 | 1.0+ | 8 | - |
| 24.1.0 | 1.15 - 1.20 | 1.0+ | 8 | - |
| 25.0.0 | 1.15 - 1.20 | 1.0+ | 8 | - |
| 25.1.0 | 1.15 - 1.20 | 1.0+ | 8 | - |
| 26.0.0 | 1.15 - 1.20,2.0 - 2.2 | 1.0+ | 8(1.x),17(2.x) | - |
| 26.1.1 | 1.15 - 1.20,2.0 - 2.2 | 1.0+ | 8(1.x),17(2.x) | - |
| 26.2.0 | 1.15 - 1.20,2.0 - 2.2 | 1.0+ | 8(1.x),17(2.x) | - |
Installation
Both Jar package and Maven dependency methods are supported.
Jar Package Method
You can download the Flink Doris Connector Jar package of the corresponding version from the Doris download page and copy it to Flink's classpath:
- Standalone mode: Place the Jar file under the
lib/directory. - Yarn cluster mode: Place the Jar file in the pre-deployment package.
Maven Dependency Method
Add the following dependency to the project's pom.xml:
<dependency>
    <groupId>org.apache.doris</groupId>
    <artifactId>flink-doris-connector-${flink.version}</artifactId>
    <version>${connector.version}</version>
</dependency>
For example:
<dependency>
    <groupId>org.apache.doris</groupId>
    <artifactId>flink-doris-connector-1.16</artifactId>
    <version>26.2.0</version>
</dependency>
Next Steps
- Follow the Quick Start to read and write a Doris table with FlinkSQL.
- Check the FAQ first when you hit an error.
