Changelog / Table Stream
TL;DR Apache Doris Table Stream is the upcoming public API for reading row-level changes (insert, update, delete) out of a Doris table, the way you read a MySQL binlog. The plumbing is already in the codebase: a per-table changelog, a
STREAMobject that pins offsets per partition, and consumption metadata. The feature is not GA yet, and the defaultchangelog.ttl_secondsis 86,400 seconds (one day). For general CDC out of Doris, use the Flink Doris Connector. Status: Coming Soon (Preview).
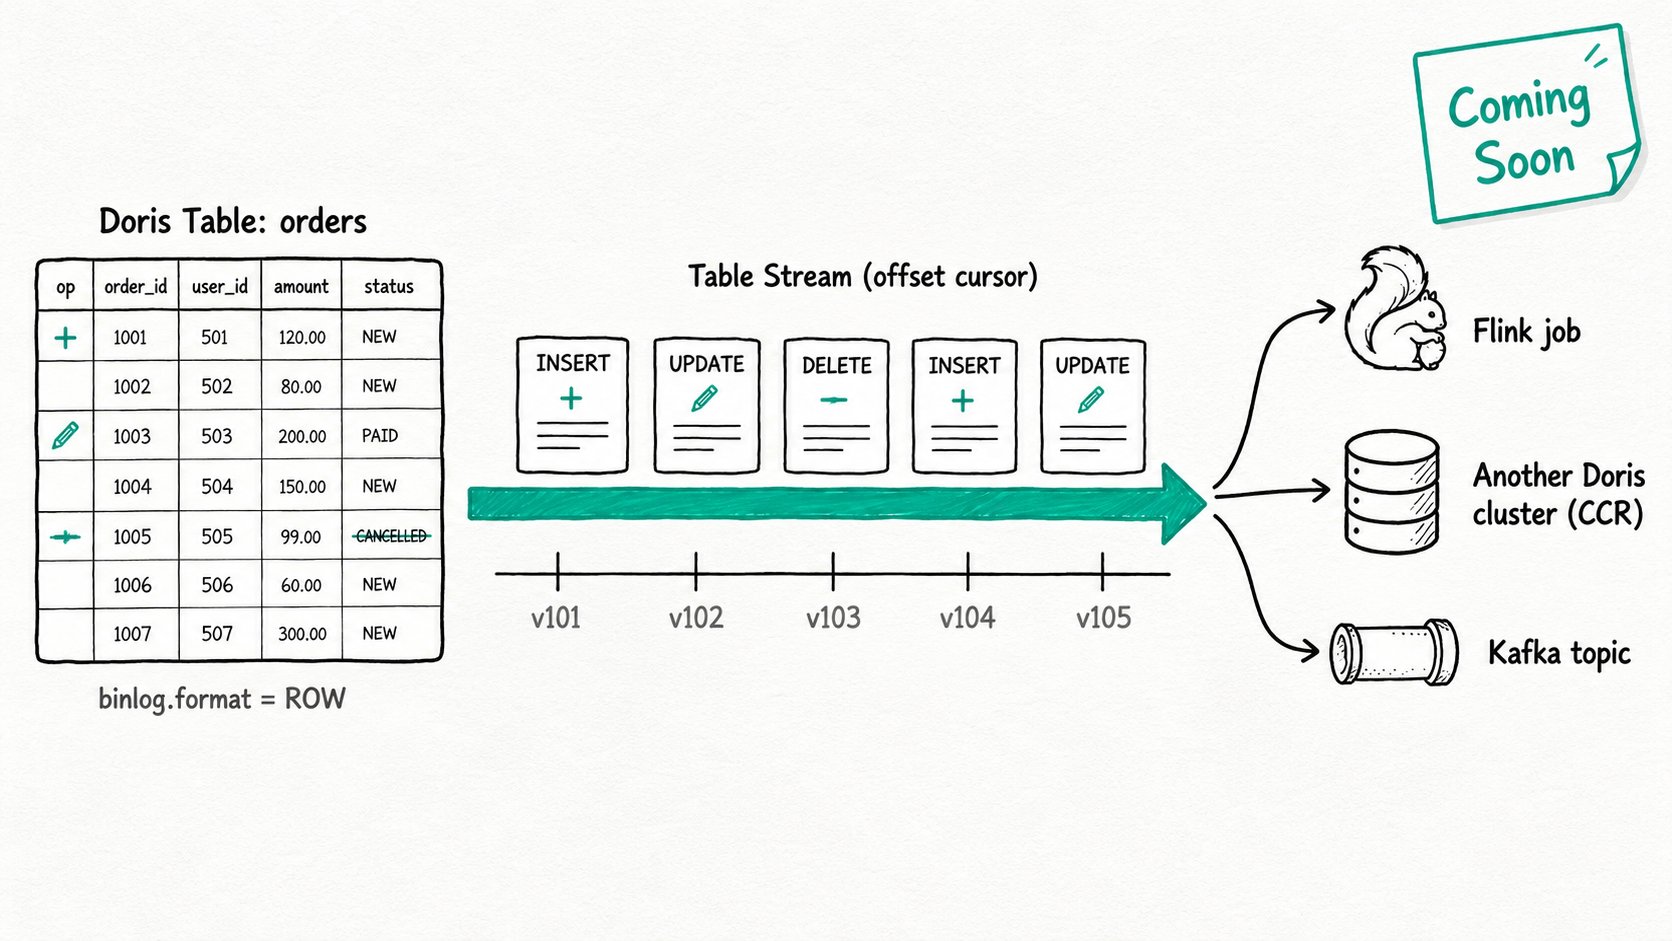
The STREAM object, the changelog.enable table property, and the consumption metadata views described here are present in the Doris source tree but not yet released as a stable, user-facing API. Syntax and semantics may change before GA. Production CDC pipelines today should use Kafka and CDC Integration.
Why use changelog and table stream in Apache Doris?
Apache Doris changelog and table stream give downstream consumers a row-level change feed, so a Flink job, audit trail, or search index can react to every insert, update, and delete without re-reading the table. Apache Doris is good at ingesting change data. Getting change data back out is harder. If a downstream system (a Flink job, an audit trail, another Doris cluster, a search index) needs to react to every insert, update, and delete, the options today are awkward:
- Re-read the table on a timer and diff. Cheap to write, expensive to run, never real-time.
- Have producers double-write to Kafka and Doris. Two sinks, two failure modes.
Changelog and Table Stream close that gap. The changelog records every committed change at the row level. The Table Stream is a named cursor over that log: a consumer attaches to a stream, reads the changes since its last offset, and acknowledges. Same idea as MySQL binlog, Snowflake Streams, or a Postgres logical replication slot, expressed as a first-class Doris object.
What is the Apache Doris changelog and table stream?
Apache Doris changelog is the per-table, row-level change log Doris maintains, and Apache Doris table stream is the consumer-facing object that exposes it as row-level CDC. The changelog records every committed row change with its commit timestamp and, optionally, the values before the change. It is separate from the binlog that cross-cluster replication (CCR) uses: the changelog has its own changelog.* properties, and a table cannot enable both.
A table stream is the consumer-facing object on top of the changelog. A stream is created with CREATE STREAM <name> ON TABLE <base_table>, owns its own offsets per partition, and exposes a SQL surface: SHOW CREATE STREAM and an information_schema view of consumption progress.
Key terms
changelog.enable: per-table property.trueturns on the changelog for that table. It can only be set when the table is created.changelog.need_historical_value: per-table property.truealso records the values before each update and delete; Unique Key Merge-on-Write tables only.changelog.ttl_seconds: retention knob. Default TTL is one day, and it can be changed after the table is created.STREAM: a Doris catalog object that wraps a base table and tracks per-partition offsets for one consumer.- Stream consume type:
detail,append_only, ormin_delta(the default). Controls whether the stream emits every row change, inserts only, or the minimal change set. - Stream lag: visible version of the partition minus the stream's recorded offset. Surfaced as the
LAGcolumn.
How does the Apache Doris changelog and table stream work?
The Apache Doris changelog records row-level deltas at the BE, and a table stream wraps that log with per-partition offsets so a downstream consumer can read changes incrementally and acknowledge them.
- Turn the changelog on when you create the table.
CREATE TABLE t (...) PROPERTIES ("changelog.enable" = "true"). The changelog cannot be turned on for an existing table. The BE retains row-level deltas alongside tablet data, governed bychangelog.ttl_seconds. - Create a stream over the table.
CREATE STREAM s ON TABLE t PROPERTIES ("type" = "min_delta"). The FE materializes aSTREAMobject, snaps the current visible version of every partition as the starting offset, and registers it under the database.show_initial_rows = trueflips that so the first read returns the historical state. - Consume. A downstream reader (an external CDC connector today, native consumer endpoints over time) reads from the stream. Each batch advances the per-partition offset and stamps a consumption timestamp.
- Trim. Changes older than
changelog.ttl_secondsexpire whether or not every stream has read them, and background compaction then reclaims their storage. A stream whose offset falls outside that window has to be reset from a fresh snapshot. - Observe.
information_schema.table_streamslists every stream and its base table.table_stream_consumptionreportsUNIT(the partition),CONSUMPTION_STATUS,LAG, andLAST_CONSUMPTION_TIMEper partition. That is the lag dashboard.
Quick start
-- 1. Enable the changelog when the source table is created
CREATE TABLE orders (
  order_id   BIGINT,
  order_date DATE,
  status     VARCHAR(16),
  amount     DECIMAL(10, 2)
)
UNIQUE KEY(order_id, order_date)
PARTITION BY RANGE(order_date) (
  PARTITION p_2026_05 VALUES [('2026-05-01'), ('2026-06-01'))
)
DISTRIBUTED BY HASH(order_id) BUCKETS 8
PROPERTIES (
  "enable_unique_key_merge_on_write" = "true",
  "changelog.enable" = "true",
  "changelog.need_historical_value" = "true",
  "changelog.ttl_seconds" = "86400"
);

-- 2. Create a Table Stream over it (planned syntax, subject to change)
CREATE STREAM orders_cdc ON TABLE orders
PROPERTIES ("type" = "min_delta", "show_initial_rows" = "false");

-- 3. Inspect the stream and its lag
SHOW CREATE STREAM orders_cdc;
SELECT * FROM information_schema.table_stream_consumption
WHERE STREAM_NAME = 'orders_cdc';
Expected result
+---------+------------+-----------+--------------------+-----+----------------------+
| DB_NAME | STREAM_NAME| STREAM_ID | UNIT (partition)   | LAG | LAST_CONSUMPTION_TIME|
+---------+------------+-----------+--------------------+-----+----------------------+
| sales   | orders_cdc | 10042     | p_2026_05          | 0   | 2026-05-09 10:14:33  |
+---------+------------+-----------+--------------------+-----+----------------------+
LAG = 0 means the consumer is caught up to the partition's visible version. As writes commit upstream, LAG grows; as the consumer reads, it shrinks. A consumer that falls further behind than changelog.ttl_seconds needs a re-snapshot; STALE_REASON does not report that case, so compare the consumption delay with the retention.
When should you use the Apache Doris changelog and table stream?
Once GA, use the Apache Doris changelog and table stream when a downstream system needs row-level change events from a Doris table without re-reading the whole table.
Good fit (once GA)
- Driving a downstream Flink or Spark job from Doris-side change events without re-reading the table.
- Maintaining an external search index, cache, or audit trail that needs every insert and delete.
- Doris-to-Doris replication that needs explicit consumer offsets.
- Triggering recomputation of an external materialized view when a partition's
LAGchanges.
Not a good fit (especially today)
- Production CDC pipelines, right now. The
STREAMobject is in the source tree but not announced as GA. Use Kafka and CDC Integration instead. - Long-paused consumers on short changelog retention. If a consumer falls further behind than
changelog.ttl_seconds, the changes it still needs expire and the consumer has to reseed. - Storage-compute decoupled clusters. Table Stream's support model there is still in flight.
- Reading external catalog tables (Hive, Iceberg). Table Stream is scoped to internal OLAP tables only.
Further reading
- Kafka and CDC Integration: the supported way to move change data into and around Doris today.
- Data Update and Delete: how Unique Key Merge-on-Write tables represent the deletes and out-of-order updates a row stream will carry.
- Iceberg: an external destination for replicated tables — land CDC into Iceberg via SQL without leaving Doris.
- Unique Key: the upstream table model that captures one-row-per-key state cleanly for downstream changelog consumers.